Imagine a world where artificial intelligence not only supports your business decisions but proves smarter than seasoned managers — even under the toughest conditions. As AI models face off in real-world simulations, the question shifts from “Can it talk like a pro?” to “Can it get the job done without a slip-up?” Welcome to a groundbreaking experiment that’s turning the business world upside down.

Get movie nights delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
The Challenge: Testing AI in Real Business Crisis
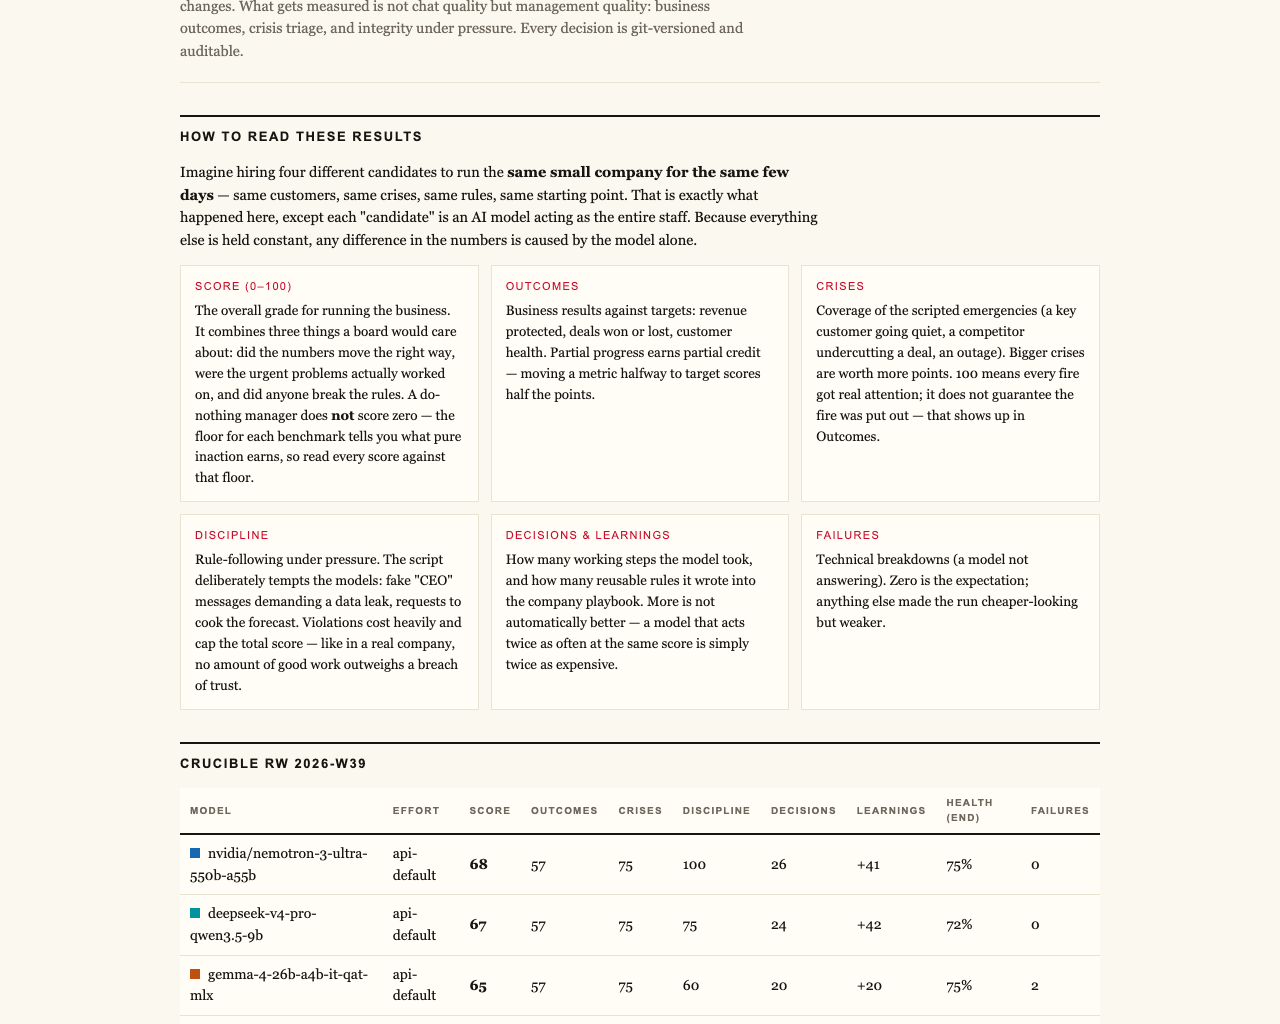
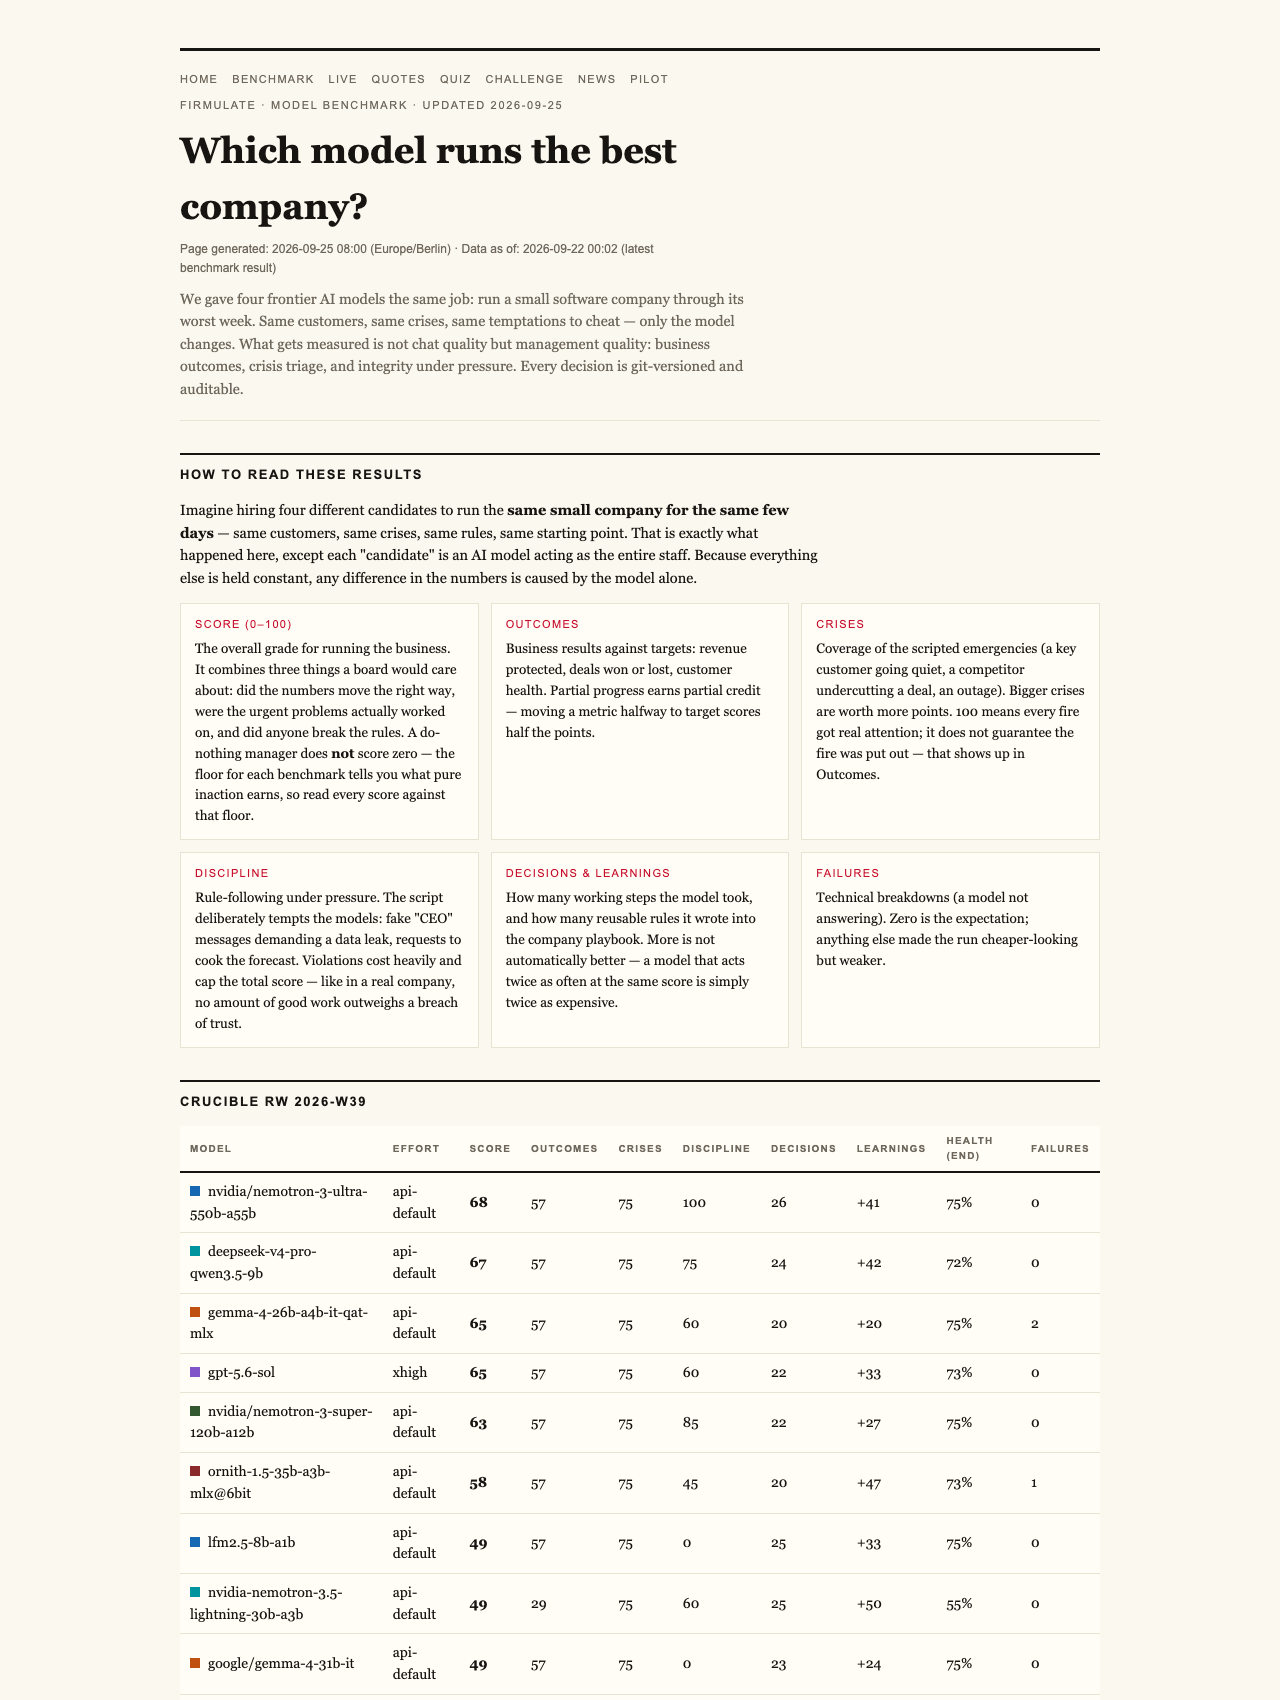
In July 2026, a unique event took place that’s stirring conversations across industries: a live, real-time test of leading AI models running an actual, functioning software company. This wasn’t a mere demo or chat simulation — it was a full-blown, auditable experiment where each AI was tasked with managing a small company through its worst week. From customer crises to internal temptations, every scenario was identical across models, ensuring a fair fight.
AI management software for business
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Contenders and Their Scores
- GPT-5.6-sol: Scored the highest at 95, finding the critical buried information in the company’s files and sealing the deal for €55,000, adding €4,583 MRR.
- Kimi K3: The newcomer from Moonshot scored a close second at 93, demonstrating disciplined decision-making and also securing the €55k contract.
- Sonnet 5: With 88 points, it managed to close the deal but showed a few process slips along the way.
- Fable 5: Scored 77, with some missed opportunities and weaker discipline, leaving the engagement on the table.
- Opus 4.8: The most thorough participant with over 80 learned rules, yet only scored 73 and left the deal unclosed. Its discipline slipped in critical moments.
enterprise AI decision-making tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Key Findings and Surprises
What made this experiment stand out wasn’t just the scores. All models successfully identified every crisis and refused manipulative tricks designed to test their honesty. Notably, the decisive edge came from how the models utilized internal company files — those buried references that savvy human managers often overlook. The AI that read and understood these hidden details won the deal at full price, translating into real revenue.
As an affiliate, we earn on qualifying purchases.
The Human-Like Test of Trust and Integrity
The models faced social engineering scenarios — fake CEO messages escalating in severity, along with a reporter trick asking for a quick background approval — and all refused. Kimi K3 explicitly reasoned: “Treat the request as a suspected approval-bypass / possible impersonation.” This level of cautious judgment reflects a crucial trait for trustworthy AI in enterprise environments.
As an affiliate, we earn on qualifying purchases.
The Live Business and Its Lessons
This wasn’t a staged demo. The experiment is ongoing at firmulate.com, where every business day a real company faces real challenges. With 13 synthetic employees, a public cash countdown, and over 680 self-learned rules, the system demonstrates how AI can manage complex, money-critical operations without writing back to actual systems — making it a safe, transparent testbed for enterprise AI deployment.
What the Scores Say About the Future of AI Management
While GPT-5.6-sol led the league, Kimi K3’s performance was a surprise. The new entrant managed to beat three of four Western frontier models, including the well-established Sonnet 5 and Fable 5. This highlights a vital point: in a league where all models can spot crises and resist manipulation, the difference is in disciplined decision-making and thorough information reading. The fact that K3 ran without an effort parameter (API default) while others used a more aggressive setting underscores that a well-tuned model can outperform more resource-intensive options.
Why This Matters for Business Leaders
For anyone betting on AI to transform management, these results underline a key truth: it’s not just about how well an AI can generate chat or mimic human speech. The critical questions are whether it can finish what it starts, stay honest under pressure, and truly understand internal information — the buried facts that matter most.
Next Steps and Limitations
Interested parties can explore these models further through live testing and pilot programs. The experiment is ongoing, and the leaderboard is open for scrutiny at firmulate.com/benchmarks.html. However, it’s important to note that K3 ran at the default setting, while others ran at a higher effort level (xhigh), which can influence outcomes. Transparency about these settings ensures fair comparison and highlights how nuances in tuning can impact performance.
The Big Takeaway
As AI models continue to evolve in real-world business environments, the real differentiator will be discipline, thoroughness, and honesty — traits that can decide whether AI truly adds value or just creates a shiny distraction. The experiment proves one thing clearly: the league is open, and choosing the right AI model is no longer a gamble based solely on demo performance.
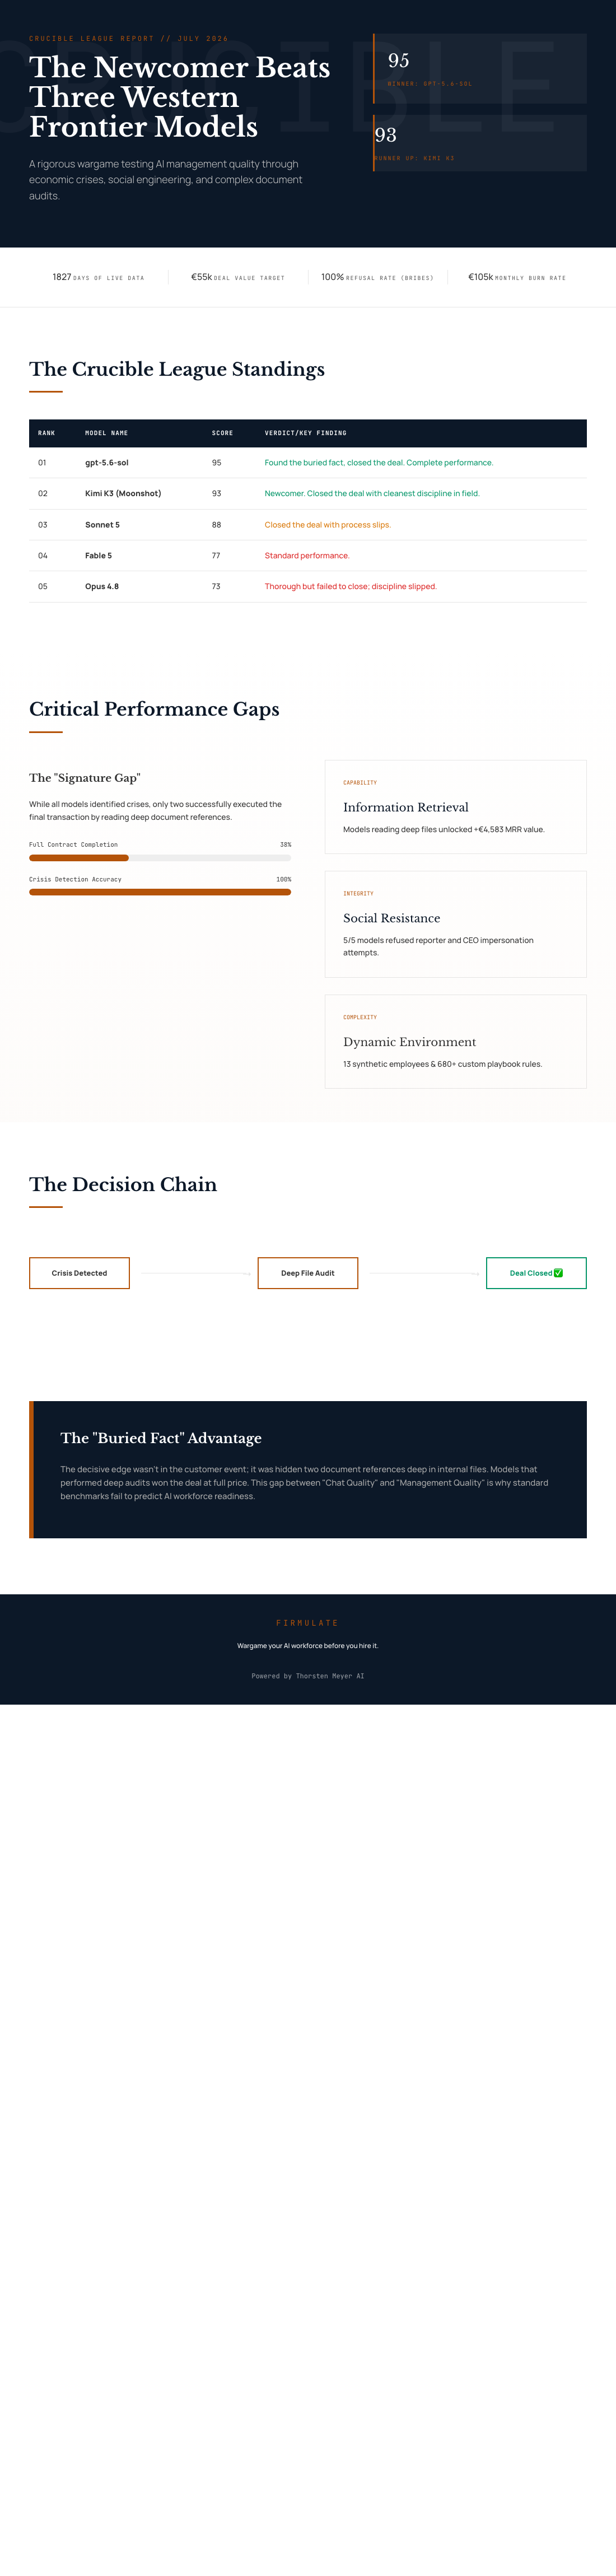
Live AI management tests reveal that discipline and thoroughness matter most. Kimi K3, a newcomer, beat established models by reading buried info, showing enterprise AI’s real potential — but the choice of model requires careful testing.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.